IEEE Transactions on Instrumentation and Measurement, 2025
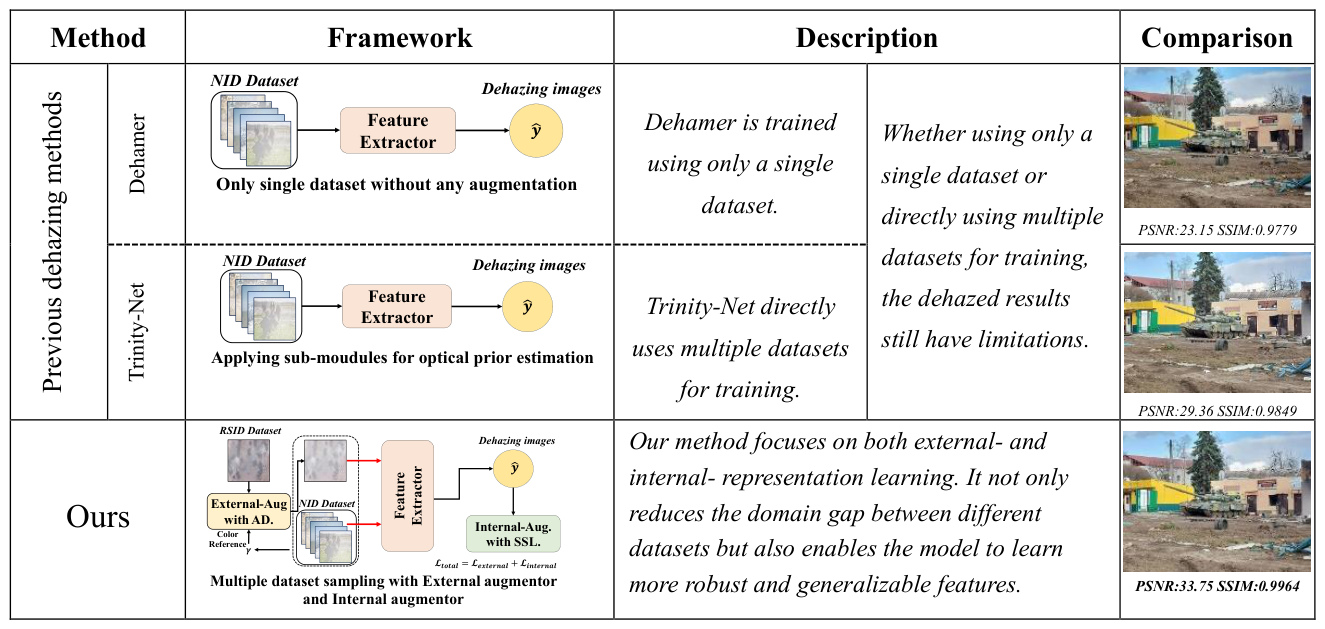
Fig. 1: Comparison with state-of-the-arts in terms of flowchart and characteristics. With the rapid development of Trans- former [11], [12], the demand for data has grown at the same time. However, the simple combination of multiple datasets achieves unsatisfactory results. To address this issue, we call for the internal- and external knowledge should be further augmented by vision alignment and self-supervised learning to perform an effective large-scale training.
Overview
Studies cross-data vision alignment and self-supervised augmentation to reduce domain gaps and improve generalizable representations for single-image dehazing.