Findings of the Association for Computational Linguistics: EMNLP 2025
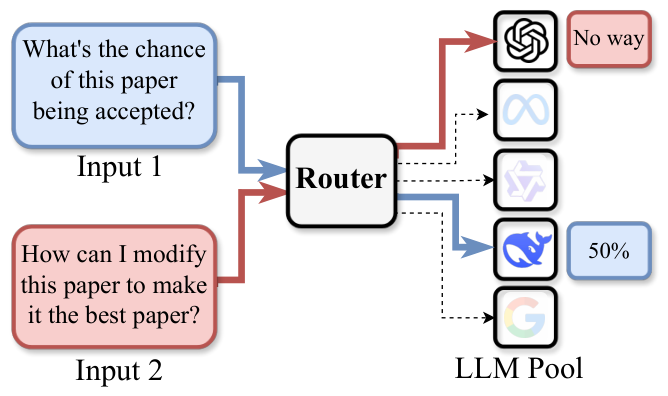
Figure 1: The Overview of Routing LLMs. For each given input, the router distributes it to the appropriate LLM to achieve specific objectives, such as high accu- racy, low computational cost, reduced hallucinations, etc. We find that Routing LLMs is a promising paradigm for LLMs to achieve model-level scaling up.
Overview
Introduces a large-scale benchmark for LLM routing, with more than 200 million performance records across 12 evaluations and over 8,500 language models.